Decentralized GPU cloud for AI
Rent a GPU with JupyterLab on it, call open models through an OpenAI-compatible API, or render a scene, on hardware we measured before you pay for it.
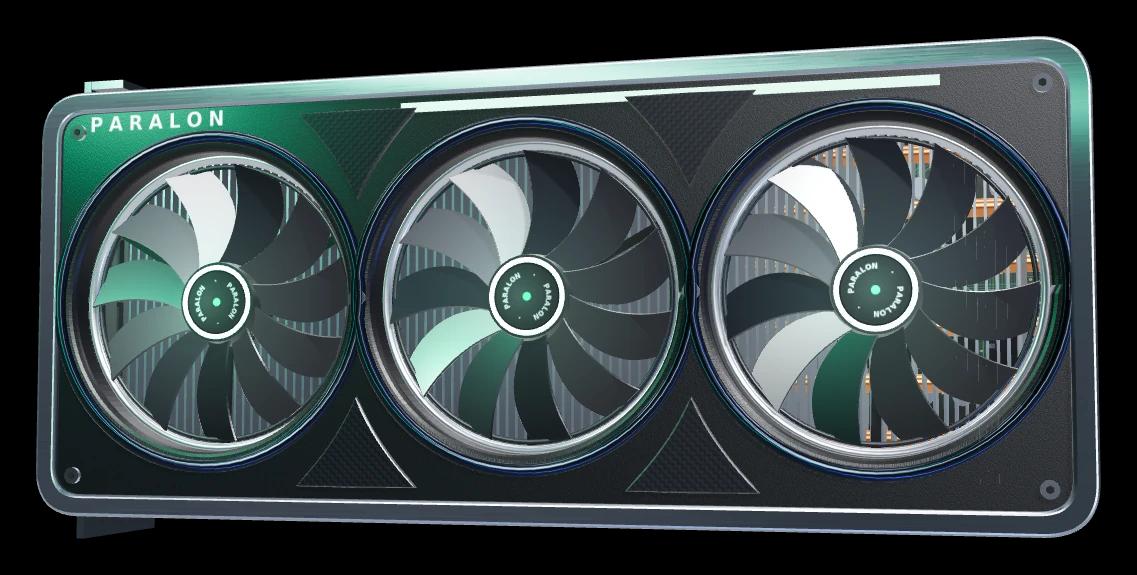
Rent it
Not a slice of a shared card. Pick a GPU, and a JupyterLab workspace is running on it about a minute later, billed by the minute until you stop it.
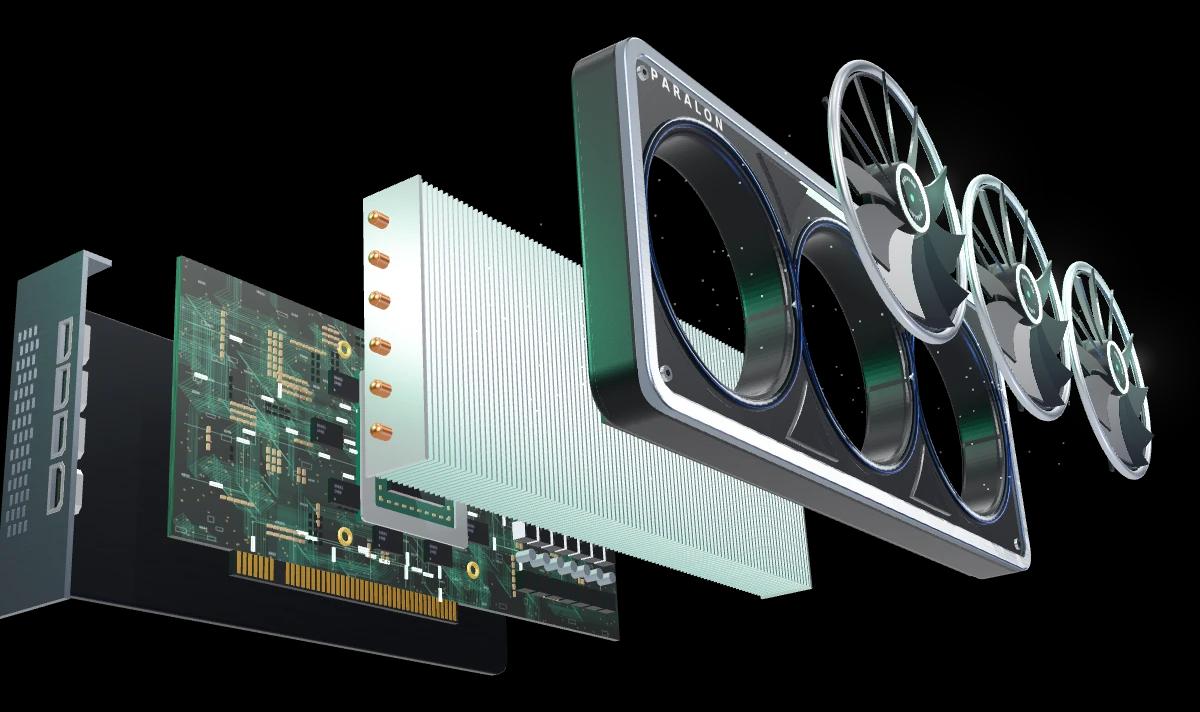
Measured
Every card is benchmarked before it is listed and again after each reboot: compute, memory bandwidth, the link it sits on. The figures are on the machine's page.
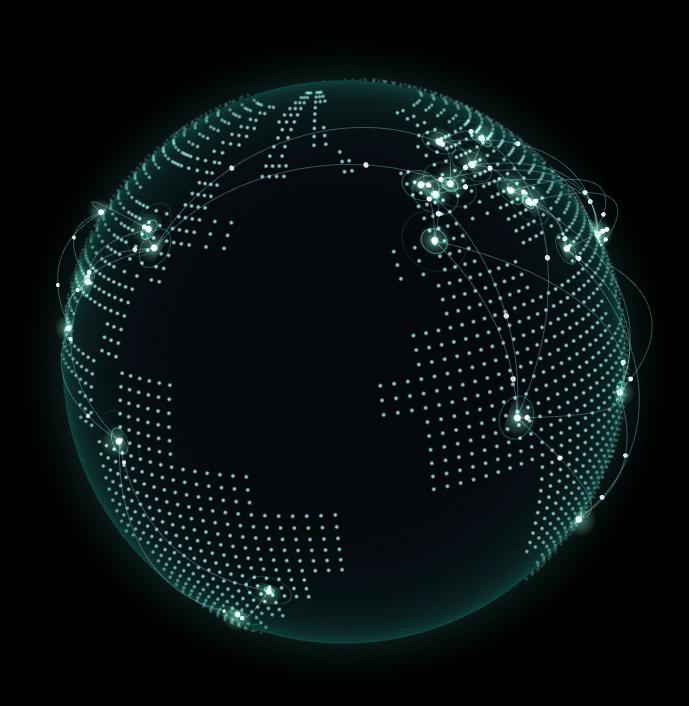
The network
The hardware belongs to independent providers around the world. Each machine and each provider carries a score from its finished rentals.
Live
This is the marketplace as it stands this minute, not a price sheet. Pick one and it is yours until you stop it.
See every machineAvailable now
Benchmarked before listingProducts
The terms
Billed by the minute
No contract and no minimum. You are not billed for the minutes a machine was down on the provider's side.
No egress fees
Pull datasets and push checkpoints without a bandwidth bill on top of the GPU price.
Spot machines
Discounted GPUs the provider may take back with two minutes' notice, for work that can be resumed.
From code, too
Rent over HTTP with the Rental API, or from Claude Code, Claude Desktop and Cursor through the MCP server.
For providers
Connect a GPU server, a workstation or a Mac. It earns when someone rents it and when it serves inference, and you decide when it is available.
- One Docker command connects the machine
- You set the price, or take the suggested one
- You keep 80% of every rental
- Paid in USDC to your own wallet
Run on the machine
docker run -d --gpus all \
  -v /var/run/docker.sock:/var/run/docker.sock \
  -v paralon-cache:/opt/paralon \
  -v /etc/machine-id:/host-machine-id:ro \
  -e TOKEN="your_token" \
  ghcr.io/paraloncloud/agent:latest
✓ Node registered and online
✓ GPU detected: RTX 4090
Sign in, add credits and start a machine. You pay for the minutes it runs and nothing else.
In partnership with
