 Benchmarks & Comparisons
7 min read
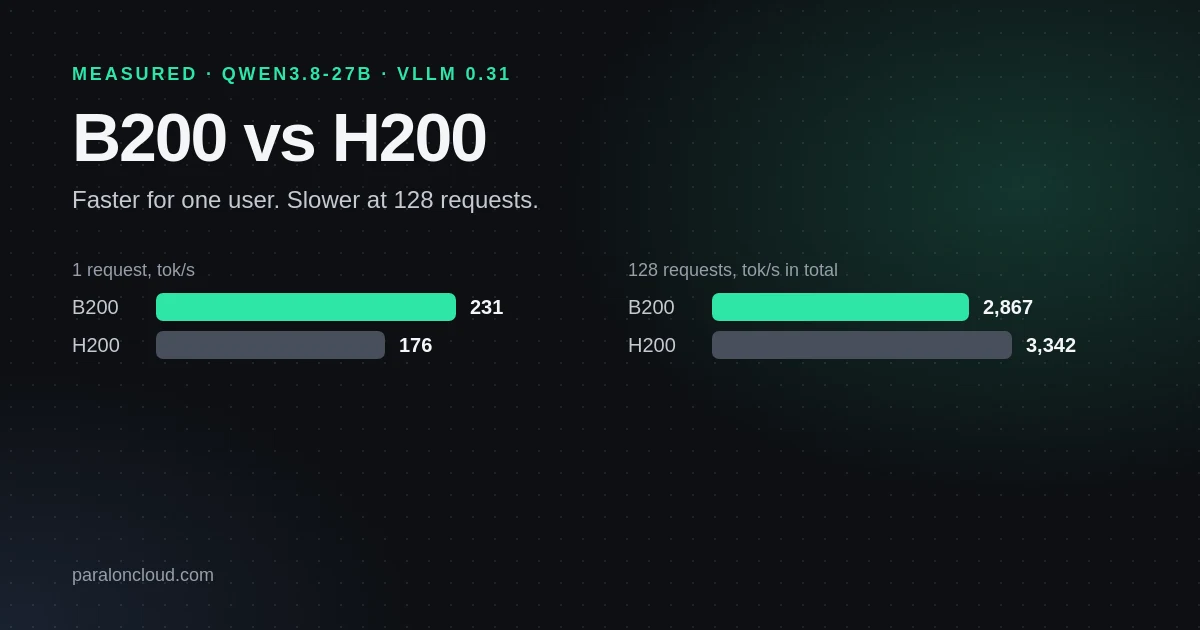
B200 vs H200 on a 27B Model: Faster for One User, Slower at 128
- 201–231 tok/s
- one request, the fastest card we have measured
- 2,867 tok/s
- in total at 128 concurrent requests, 14% under the H200
Tag
7 articles tagged with “Gpu”
Benchmarks & Comparisons7 min read
 Benchmarks & Comparisons
7 min read
 Benchmarks & Comparisons
8 min read
 Engineering
9 min read
A new RTX PRO 6000 joined our network and got a quarter of the traffic of a pair of RTX 4090s it outperforms 3x under load. The GPU-name table had no entry for it, and our measured correction could not see the difference, because per-request speed is nearly equal on the two. What we replaced both with, the cold-start mistake we made on the way, and two routing bugs the new weights exposed.
Read Guides & Tutorials
7 min read
Qwen3.8-27B is trained on 262,144 tokens of context, and a full-length request costs only about 9.3 GiB of KV cache in vLLM, because three layers in four keep no per-token cache at all. Here is the arithmetic, what we measured on a 96 GB card and a pair of 24 GB cards, a table from 24 to 96 GB, and why we would not stretch it to 1M with YaRN.
Read Benchmarks & Comparisons
8 min read
 Benchmarks & Comparisons
8 min read
We had a rule that a model which fits on one GPU should run as one replica per GPU. On a two-RTX-4090 machine with a 27B model, that rule was wrong by a factor of two to four, and the reason was not the parallelism at all. Here are the measurements, the rule that replaced it, and how the router now sends a 40k-token prompt to the worker that can hold it.
Read